
MiniMax M3.1 Flash: Free Until Oct 22
MiniMax's new coding-agent model is free to try until Oct 22 on three providers — here's what the independent numbers say before the weights land.
Yesterday, MiniMax released M3.1 Flash — a model built for agentic work: writing code, operating software on your behalf ("computer use"), and cybersecurity tasks. The headline for you: it's free to try until October 22 on OpenRouter, Vercel's AI Gateway, and Ollama — and the open weights that would let you run it on your own computer are reportedly landing on October 23.
If you use a coding agent and watch the bill, or you run models locally and want to know whether this one deserves your machine's time, this post is for you.
What happened
MiniMax launched M3.1 Flash on October 19, 2026, through its own API, the M Plan subscription, and MiniMax Code. The price list is aggressive: $0.15 per million input tokens, $0.60 per million output tokens, and $0.015 for cached input — about half of what DeepSeek charges for its competing V4.1 Flash model, which launched just three days earlier.
MiniMax claims the model cuts the cost of a finished agent task by ~70% compared with its predecessor M3. Treat that as a company claim: MiniMax's own comparison on the Artificial Analysis task set shows $0.22 per task versus $0.51 for M3 — a 57% reduction, not 70%. The truth is probably somewhere in that range and depends heavily on how many steps your agent takes.
The specs that are confirmed: a 1 million token context window (text, image, and video in; text out), and reasoning that is always on — you can't disable it, you just pick an effort level from low to max. A 1M context matters for agents because a long multi-step session stays in memory instead of getting cut off.
Then there's the rabbit. For ten days, an anonymous model called "Space Bunny" sat at #1 on OpenRouter's charts, processing 56.7 trillion tokens — the most of any stealth model OpenRouter has run, according to OpenRouter's own announcement. MiniMax has now confirmed Space Bunny was an early build of M3.1 Flash, and says the stealth run processed 200 trillion+ tokens. That anonymous public test is worth more than most launch-day benchmarks: real users, real prompts, no cherry-picking.
What the independent numbers say
Artificial Analysis ran its own tests, and the gap between MiniMax's marketing and the measurements is worth seeing plainly:
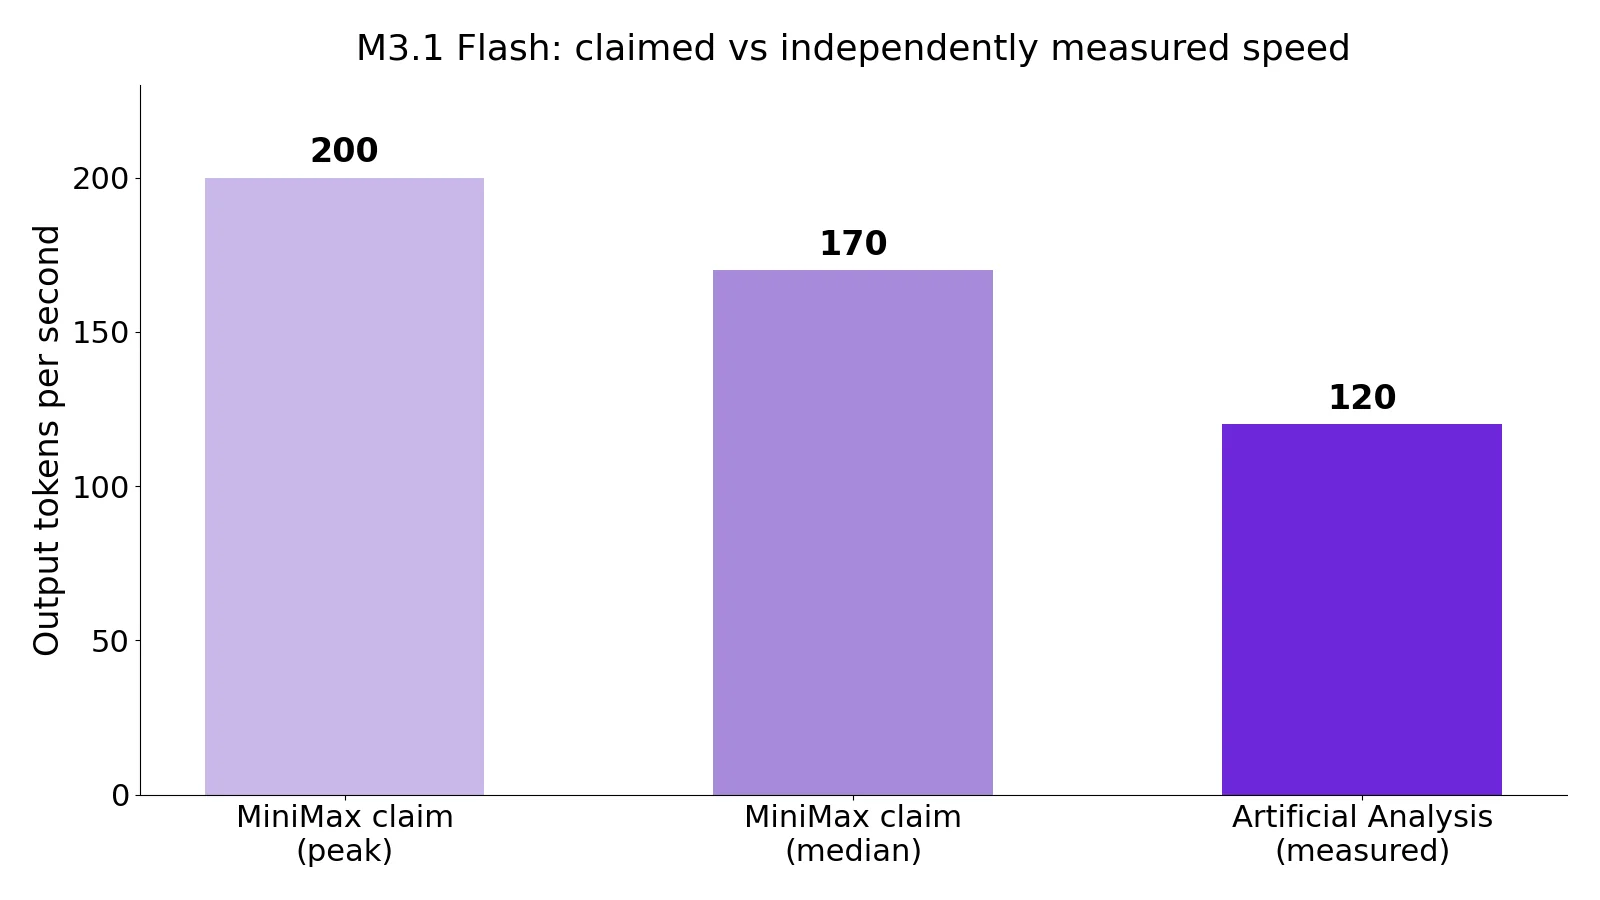
- Speed: MiniMax claims over 200 output tokens per second (median 170+). Artificial Analysis measured 120 tokens per second, with 1.08 seconds to the first token.
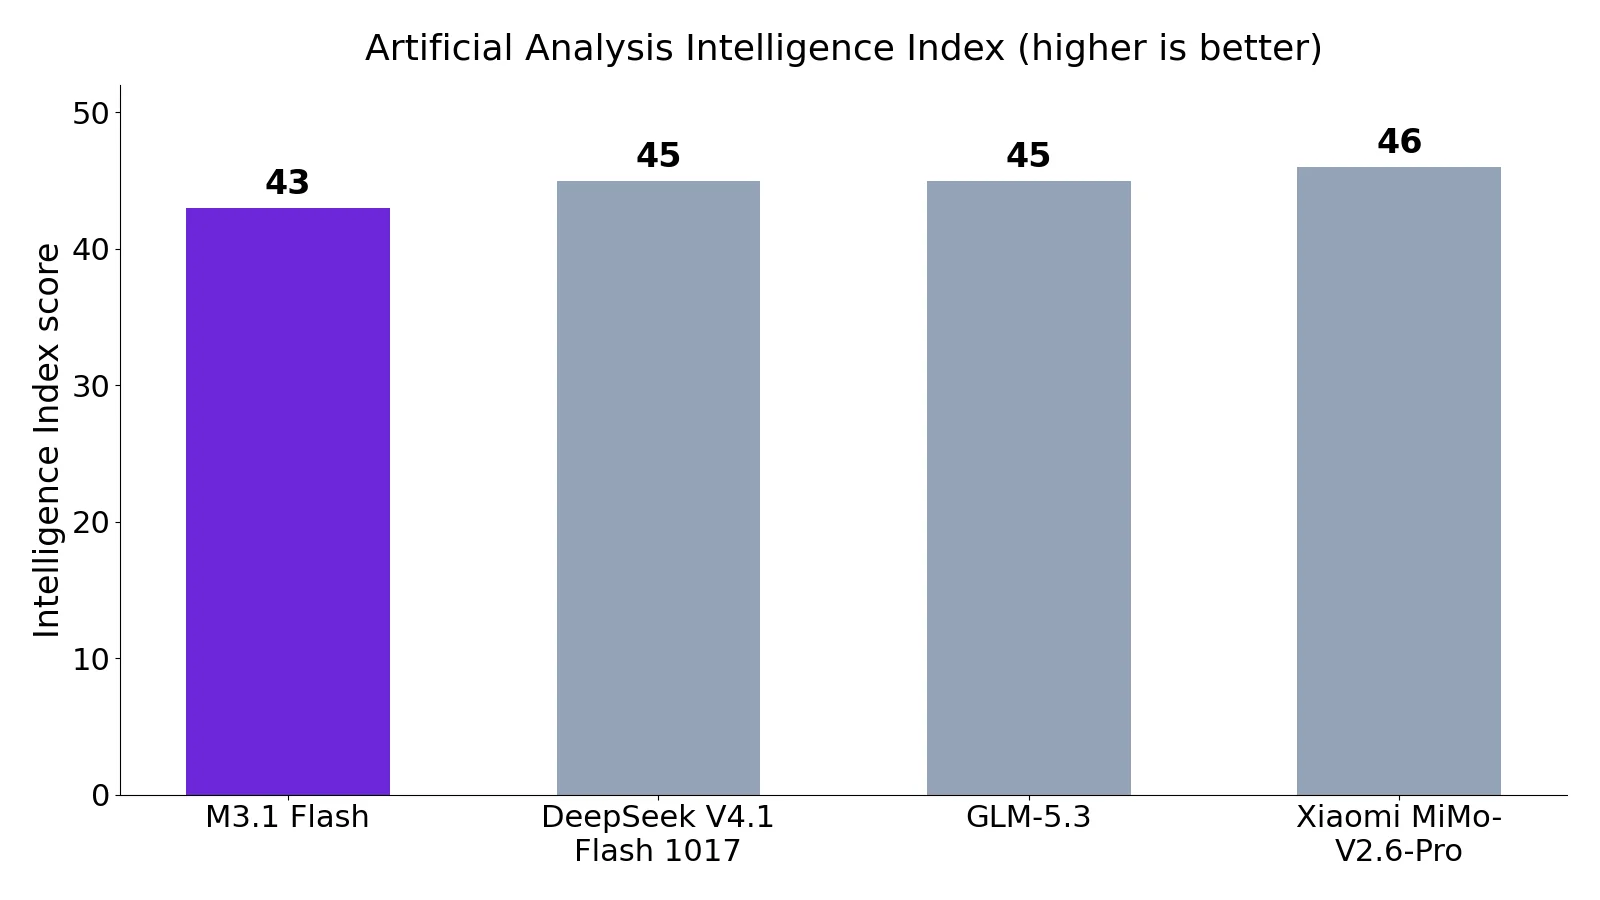
- Intelligence: Artificial Analysis scores it 43 on its Intelligence Index — up from 29 for the original M3, but a couple of points behind the direct rivals: DeepSeek V4.1 Flash 1017 at 45, GLM-5.3 at 45, and Xiaomi's MiMo-V2.6-Pro at 46. (We covered DeepSeek V4.1-Flash three days ago if you want the head-to-head.)
- Verbosity: Artificial Analysis calls the model "very verbose" — it burned roughly 180 million output tokens to complete the index, against a 99 million median for its class. Verbose models cost more than their price list suggests.
- Honesty about not knowing: a 93% hallucination rate on Artificial Analysis's omniscience benchmark, reported via VentureBeat. That doesn't mean 93% of answers are wrong — it means when the model doesn't know something, it almost always guesses instead of saying so. Use it for work you can check, not for facts you can't.
Free until October 22
Three free windows are open right now:
- OpenRouter — 72 hours free from October 19 on the
minimax/minimax-m3.1-flash:freeendpoint (rate-limited, as free tiers are). - Vercel AI Gateway — free until October 22, as
minimax/minimax-m3.1-flash. It works with coding agents like Claude Code, Cursor, and Codex vianpx vercel ai-gateway setup. - Ollama — free until 23:59 UTC on October 22, per Ollama's newsletter.
The model weights — the files you'd need to run it yourself — are reportedly arriving on October 23. That's from circulating reports, not MiniMax's official announcement, which only says "later." MiniMax has also not confirmed the parameter count or the license, so treat any hardware math you see online as speculation for now.
What it means if you run AI on your own computer
Right now: nothing you can install. No weights, no confirmed size — so anyone telling you exactly which GPU it needs is guessing. Once the weights land, that's the moment to check your computer and see whether your machine can actually run it.
What you can do this week is the smart version of shopping: test-drive it free in the cloud before deciding whether it's worth your disk space and RAM. That's a rare opportunity — most models ask you to commit hardware first and discover the quality later.
Two practical notes if you try it:
- Plan around 120 tokens/second, not 200. The independent measurement is the number to budget with. It's still brisk — but the free tiers are shared with everyone else trying it this week, so your mileage will vary.
- Build verification into the workflow. A model that guesses when it doesn't know is fine for coding with a test suite or automation with a checkable final state. It's a poor fit for answering factual questions you can't verify.
The bigger picture: the price race between Chinese labs is now the main story in affordable AI. M3.1 Flash undercuts DeepSeek's model on price while scoring within two points of it on the independent index. Whether it earns a place on your machine comes down to one question the October 23 weights will answer: how big is it, and what license does it carry?
Try it yourself
Pick one of the free routes before October 22 ends — OpenRouter's :free endpoint is the lowest-friction start if you just want to chat with it, and Vercel's AI Gateway is the route if you want it inside your coding agent.
Then, when the weights reportedly land on the 23rd, come back and check your computer to see if your setup can run it locally. I'll update our model data once the size is confirmed — and if you tried Space Bunny back when it was anonymous, I'd genuinely like to hear how it behaved for you.
Sources
- MiniMax M3.1 Flash now available on AI Gateway for free, Vercel
- MiniMax Releases M3.1 Flash AI Model With Substantial Cost Cuts and Better Performance, Winbuzzer
- MiniMax M3.1 Flash: price, benchmarks and DeepSeek comparison, madrobot.blog
- MiniMax Launches M3.1 Flash for Fast, Low-Cost AI Agents, aistify
- MiniMax M3.1 Flash: Comparing Its Leaderboard Standing With Our Test Results, digitechbytes
- MiniMax M3.1 Flash: A Free Mystery Model, a Big Price Cut, and One Number You Shouldn't Ignore, zyvop
- MiniMax M3.1 Flash Cuts AI Agent Costs by 70%, technology.org
- MiniMax M3.1 Flash: Space Bunny Revealed and Tested, michaelleung.info