
Try Reflection's 501B Beam for free on Ollama Cloud — no GPU farm required
For a limited time, you can run a 501-billion-parameter open model from your terminal with one command — zero data retention, no 280 GB of GPU to buy.
A 501-billion-parameter frontier-class open model just became something you can try in a terminal window. On October 16, Ollama announced that Reflection's Beam is available on Ollama Cloud — free for a limited time, with full zero data retention. That is a genuine window: test-driving the West's first 500B+ open agent model costs you nothing and about one command.
What happened
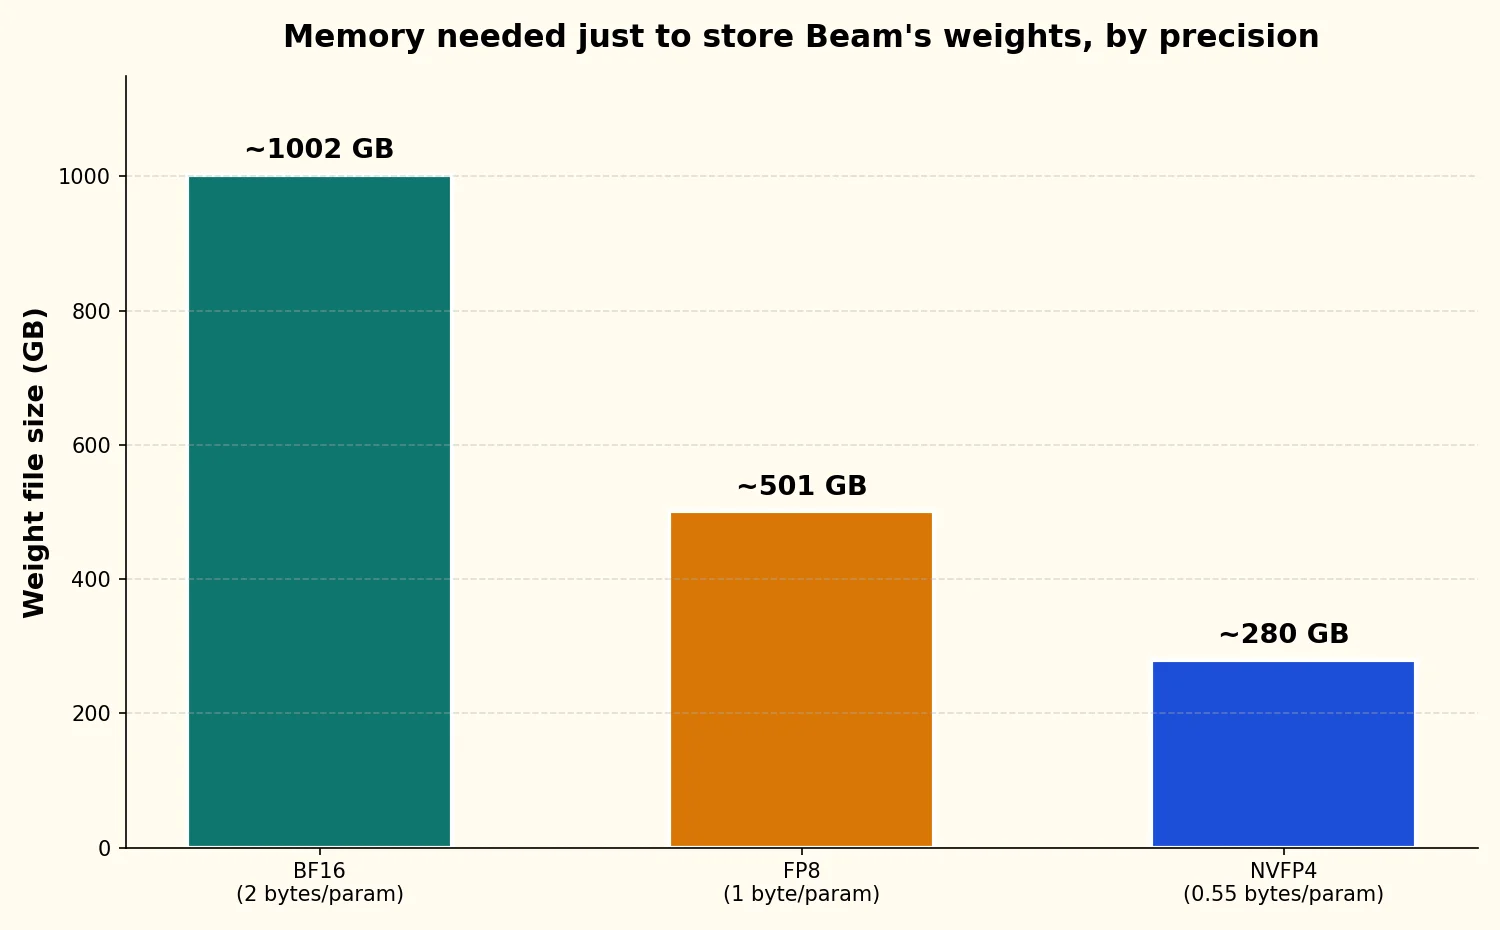
Reflection AI released Beam, its first open-weight model, on October 5 — 501B total parameters, 23B active per token, a 1M-token context window, and an Apache 2.0 license. Running that model yourself is a data-center affair: Reflection's own write-up notes the NVFP4 build squeezes the full weights to about 280 GB, and recommends four 720 GB-class GPUs to serve it with room for long contexts. Nobody is doing that on a home PC.
The October 16 move changes the calculus. Ollama is now serving Beam through Ollama Cloud, free while the launch window lasts, with full zero data retention — Ollama says your prompts are not stored. The model is also on Vercel's AI Gateway free for the launch period, but the Ollama route is the one that drops straight into the tool local-AI people already have installed.
Why this matters for you
Three practical takeaways:
- You can benchmark a 500B-class model against your own workload this week. Beam is built for coding, reasoning, and long-horizon agent tasks — the "read the repo, edit the files, run the tests" loop. Reflection reports 81.6% on SWE-Bench Verified and 80.1% on Terminal Bench v2.1 (BF16 checkpoint, its own runs). Numbers like that are worth verifying against your code, and the free window makes that cheap.
- It shows what "open" buys you even when you don't self-host. The Apache 2.0 license means anyone can fine-tune and commercialize it — but the free cloud tier means you don't need the 280 GB of VRAM first to decide whether it's worth the effort.
- Zero data retention answers the privacy question for once. Most free cloud tiers quietly keep your prompts. Here the endpoint runs with full ZDR, which matters if you want to point it at real code instead of toy examples.
The chart below is the reason this matters: weight-file sizes alone, no KV cache included.
How to try it
Update Ollama to the latest version first, then:
ollama run beam:cloud
That's it — no download, no model pull, no local inference. The :cloud suffix tells Ollama to route through Ollama Cloud instead of your machine. You will need an Ollama account signed in; cloud requests bill against your account when the free window ends.
Ollama also wires Beam into the coding agents people already use:
ollama launch claude --model beam:cloud
ollama launch codex --model beam:cloud
ollama launch opencode --model beam:cloud
If you want a first test, try something with a clear pass/fail: hand it a small repo task you already solved, and compare its result to what your usual model produced. A few hours of that tells you more than any benchmark table.
The honest limits
- "Limited time" has no end date announced. Ollama says "for a limited time only" and hasn't said when pricing kicks in or what it will be. Treat this as an evaluation window, not a permanent free tier.
- It's still cloud. Your prompts travel to US-hosted Ollama Cloud. ZDR is good, but it's not the same as a model that never leaves your machine. Anything with secrets should stay on a model you run locally — the checklist helps you figure out which workloads genuinely need that.
- Benchmarks are Reflection's own. SWE-Bench Verified at 81.6% and the rest come from the release materials. Independent reproductions haven't landed yet, and a model tuned for benchmark harnesses can still surprise you on messy real code.
- Self-hosting remains a data-center sport. Even the 280 GB NVFP4 build is beyond consumer GPUs, and the BF16 release is a full 1 TB of weights. The free cloud tier is how almost everyone will meet this model.
My read: run your own small evaluation while the window is open. The cheapest way to decide whether a 501B open model deserves a place in your stack — hosted or, one day, self-hosted — is to measure it on your work, not to admire its spec sheet.
Sources
- Ollama blog: "Reflection's Beam is freely available on Ollama for a limited time" — free launch window, zero data retention,
ollama run beam:cloud, coding-agent launch commands (Oct 16, 2026) - Reflection: "Beam is now available" — 501B total / 23B active parameters, 1M-token context, Apache 2.0 license, BF16/FP8/NVFP4 formats, speculative-decoding drafter, 40+ launch partners
- Intelligibberish daily roundup (Oct 17, 2026) — NVFP4 shrinks BF16 from ~1 TB to ~280 GB per Reflection's Hugging Face write-up; four 720 GB GPUs recommended for serving with long contexts
- Vercel changelog: Reflection AI's Beam now available on AI Gateway for free — free launch-period access on AI Gateway with 1M context