
Mistral Large 4 ('Le Chonk'): why a 1-trillion-parameter open model still won't fit on your PC
France's Mistral just previewed a 1-trillion-parameter open-weight model. The headline number is exciting; the memory math says your home PC can't run it.
France's Mistral AI announced Mistral Large 4 — nicknamed "Le Chonk" by the company itself — on October 6, 2026. It is a natively multimodal, open-weight model with 1.05 trillion total parameters and 49 billion active per token, per Mistral's own documentation. The model is live now only as an API preview; Mistral says the weights ship by the end of October. So the question for this blog: when those weights land, could you actually run it on your own machine?
The honest answer is no — and the math behind it is a skill worth learning, because it lets you judge every future giant model the same way.
Total vs. active: the number that actually matters
Large 4 is a mixture-of-experts (MoE) model. Think of it as a building with many specialist offices, but only a few offices' lights are on for any single task. Mistral reports 1.05 trillion total parameters, but only 49 billion active per token — roughly 1 in 20 parts of the network wake up for each word it writes.
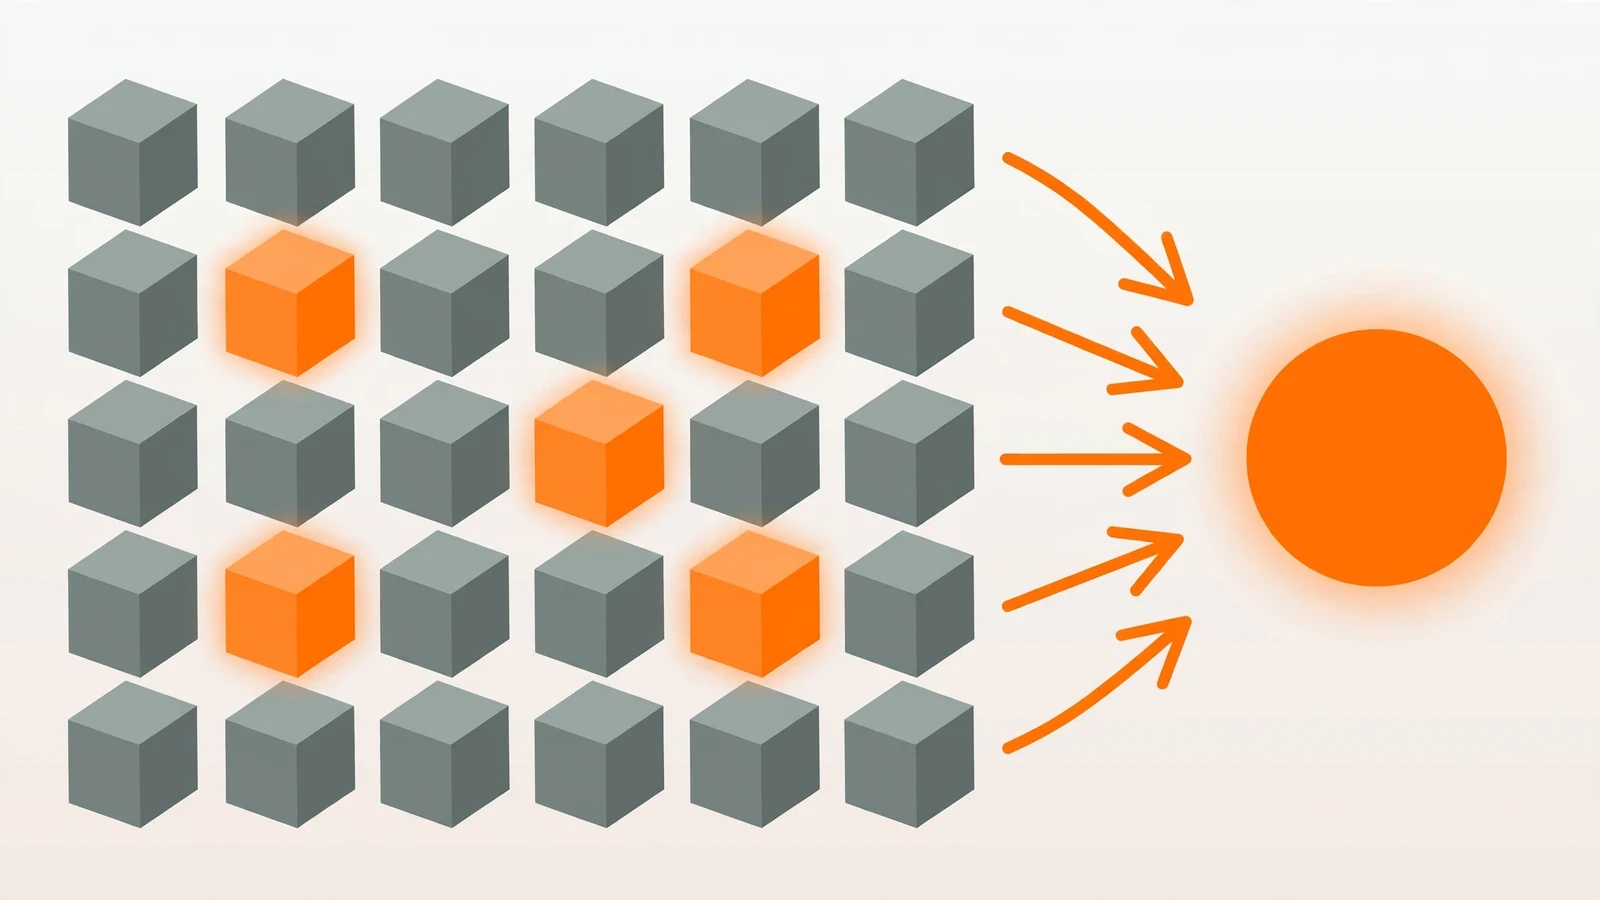
That active number tells you how much compute each answer costs — roughly what a 49B dense model would need per token. But here is the catch that marketing glosses over: every parameter still has to live in memory, active or not. The lights-off offices still take up floor space. So the memory bill is set by the 1.05 trillion, not the 49 billion.
The honest memory math
The rule of thumb: a model needs about half a byte of memory per parameter at 4-bit quantization, plus a little overhead — call it 0.55 bytes per parameter for a safe estimate. At 8-bit, double it. That estimate covers only the weights; the KV cache and runtime add more.
- Mistral Large 4 (1.05T): ~578 GB at 4-bit, ~1.15 TB at 8-bit.
- For comparison: Reflection Beam (501B) ~276 GB, DeepSeek V4 Pro (1.65T) ~908 GB, Qwen3.8 Max (2.4T) ~1,320 GB — all at 4-bit, weights alone.
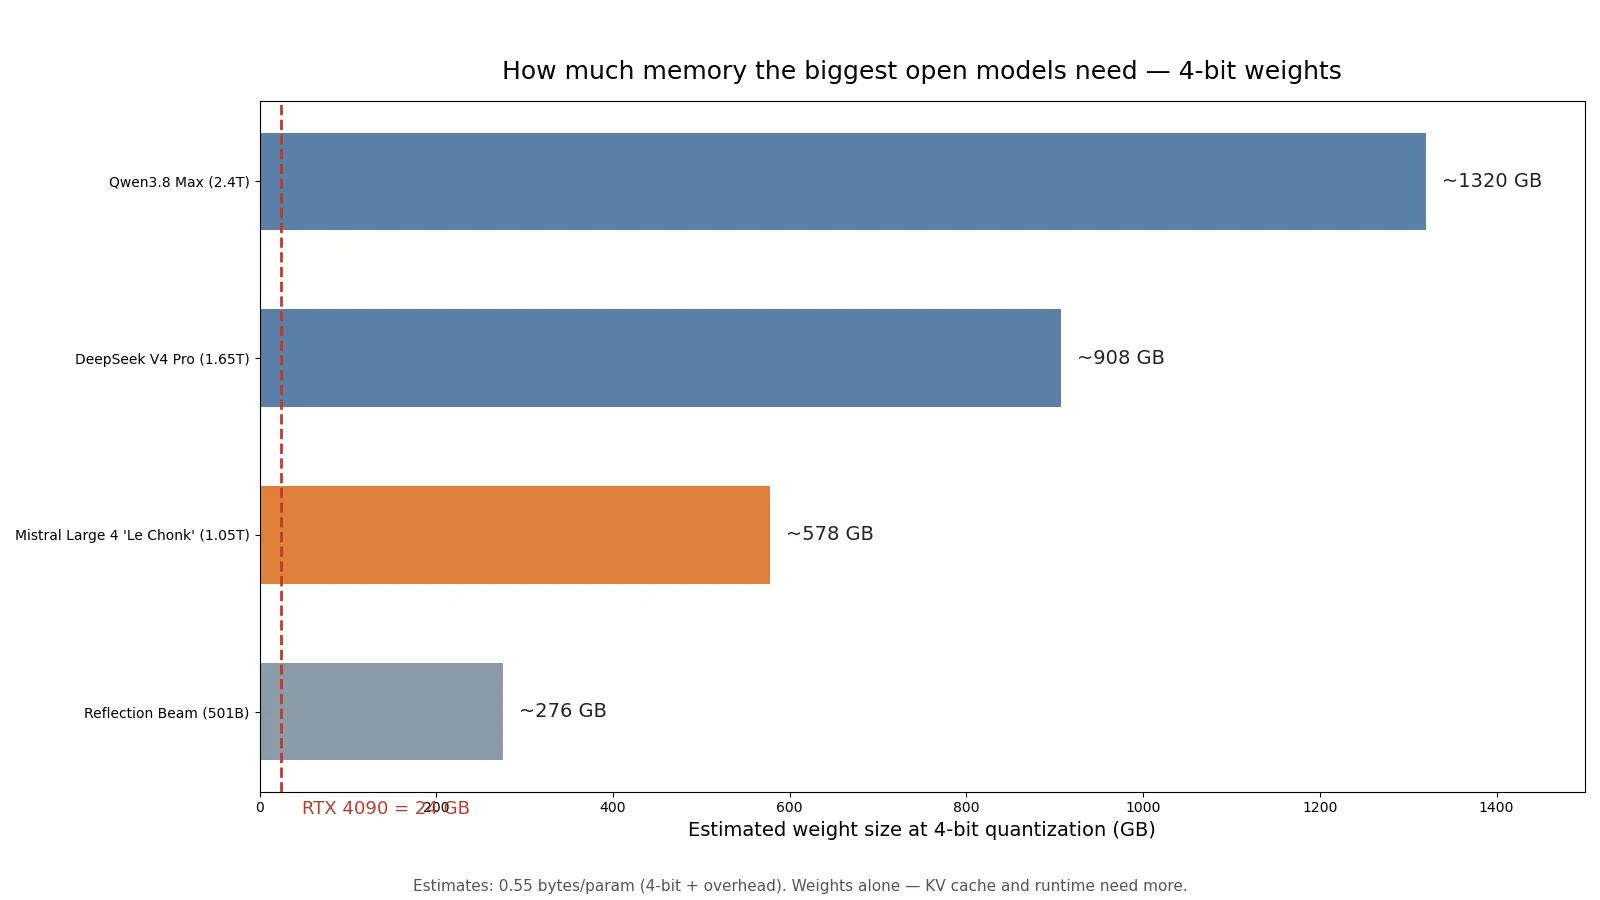
The red line in the chart is an RTX 4090 with 24 GB. A fully loaded M4 Max machine with 128 GB of unified memory — the biggest consumer setup most readers own — holds less than a quarter of Le Chonk's 4-bit weights. Serving this model takes a multi-GPU server: eight 80 GB GPUs give 640 GB, which barely fits the 4-bit weights before the KV cache eats the rest. Until community quants or distills appear, this is a datacenter model.
What this changes for you today
Nothing on your machine — but three things worth doing:
- Use the same math on every announcement. When the next "X trillion parameters" headline drops, multiply by 0.55 bytes for 4-bit. If the answer dwarfs your hardware, it's a server model, full stop. The active-parameter count tells you how fast it thinks; the total count tells you how much room it takes.
- Watch the distills, not the giant. Big labs now routinely release smaller distilled versions of frontier models — a future 49B-class Le Chonk distill would need roughly 28 GB at 4-bit, which fits a 32 GB GPU or a 64 GB unified-memory Mac. That's the tier that actually reaches your desk.
- Try it as an API today. Mistral's public preview is live on its platform, so you can judge the quality for yourself while the weights are pending — just know an API trial tells you nothing about local performance.
Also keep your eyes on Mistral's Hugging Face organization: as of the announcement, no Large 4 checkpoint had appeared there, so the weights drop is a "watch, don't wait" situation. And remember that Mistral's benchmark claims — strongest open model outside China "by a substantial margin," 93% on Cybench — are the company's own numbers. Independent evaluations will land after the weights do, and those are the ones worth trusting.
Don't plan around it yet
Le Chonk is a schedule, not a download. The weights are promised by end of October under an open-weights release, but the exact license terms come with the weights — Mistral's previous open release, Large 3, shipped under Apache 2.0, but nothing is confirmed for Large 4 until the files land. Don't reorganize your local setup or your budget around a model you can't pull yet. If you want to know what your current machine can run today, use /check and the /learn hub instead — the giant models will still be there when they're actually downloadable.
Sources
- Mistral Large 4 announcement — Unite.AI (Oct 6, 2026) — 1.05T total / 49B active, 1.6B vision encoder, 1M-token context, documentation details, and open-weights timeline
- Mistral Previews 1T-Param Open-Weight Large 4 'Le Chonk' — AI Weekly — ~4,000 Grace Blackwell GPUs, API preview, benchmark claims (Cybench 93%, vulnerability reproduction 82%)
- Mistral Large 4 "Le Chonk": 1-trillion-parameter model, weights due Oct. 27 — AI Stock Wire — weights timeline, CEO statements, Artificial Analysis Cyber Index claims
- Mistral Large 4 "Le Chonk": 1.05T Param AI Model — Tech Insider — comparison sizes: DeepSeek V4 Pro (1.65T/49B active), Qwen3.8 Max (2.4T/95B active)
- Reflection AI's Beam: Why 23B Active Parameters Matter More Than 501B — DEV Community — Reflection Beam (501B total, 23B active)